So You Wanna MLOps, Huh?
Alright, let’s talk MLOps. Fancy buzzword, right? Sounds like something you’d put on a resume to sound smart at parties. But honestly? It’s just about making sure your machine learning models don’t fall over and die the second real users touch ‘em.
Let’s start with some pretty pictures (a.k.a. diagrams).
What Even Is MLOps?
MLOps = Machine Learning + Operations. Basically, it’s the stuff you gotta do to get a model out of your Jupyter notebook and into the real world without everything catching on fire.
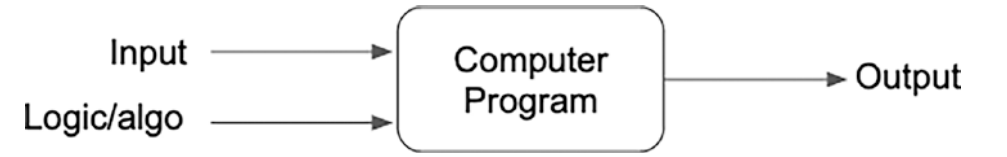
Let me explain with some equations that I definitely didn’t stay up late thinking about:
Normal apps are simple — you shove input in, some code does stuff, output comes out. That’s it. Boring but reliable.
Machine learning? Now we’re cooking with gas. Instead of writing rules by hand, you throw data at an algorithm and it builds a model. Magic. Then later you feed that model more data and it spits out predictions like some kinda digital fortune teller.
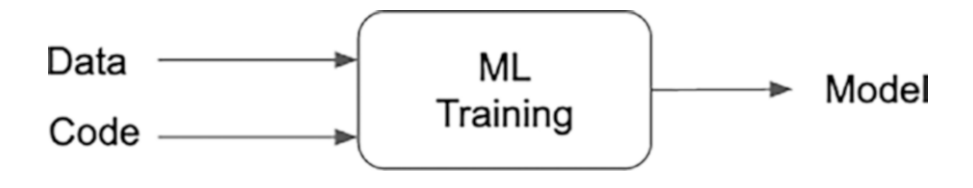
But here’s the thing — models are needy. They need tuning. Take K-Means clustering: you’re grouping data points into clusters, but how many clusters? That’s a hyperparameter you gotta fiddle with. Sometimes you need 3, sometimes 10. It depends on what your data looks like and what you’re trying to figure out.

Why Should You Care?
Building a model is easy. Keeping it alive in production is where the pain begins. Without MLOps, this is your life:
- Your model gets old and crusty because data changes over time (concept drift, anyone?)
- Deploying is a manual nightmare of copying files and crossing your fingers
- Your model’s performance goes to crap and you don’t notice for weeks
- Nobody can reproduce your results because you forgot which Python version you used
MLOps fixes all that. Or at least tries to. It’s like having a responsible adult watching over your ML pipeline.
The Good Stuff — Key Components
1. Data Management
- Keeping track of which dataset version you used (because you will forget)
- Making sure your data isn’t garbage
- Building pipelines to transform raw data into something useful
2. Model Development
- Logging every experiment so you can look back and cringe at your early attempts
- Tuning hyperparameters without going insane
- Actually testing your models before shipping them
3. Deployment
- Wrapping models in containers so they run the same everywhere (thanks Docker)
- Automating the whole deploy pipeline
- Setting up APIs so other apps can talk to your model
4. Monitoring & Maintenance
- Checking if your model is still doing its job
- Detecting when the real world changes and your model doesn’t
- Auto-retraining before things get ugly
How MLOps Works (The Lifecycle)
- Data Prep — Collect data, clean it, cry about how messy it is, clean it again
- Training — Throw algorithms at the data and hope for the best
- Validation — See if your model is actually smart or just memorizing stuff
- Deployment — Push it to prod and hold your breath
- Monitoring — Watch it like a hawk
- Retraining — Do it all over again because the world changed
Spoiler: you’ll spend most of your time on step 1.
Tools of the Trade
- MLflow — Tracks your experiments so you don’t lose them in the void
- Kubeflow — For when you need Kubernetes to orchestrate your ML chaos
- DVC — Git for your data
- Weights & Biases — Pretty dashboards for your training runs
- Cloud stuff — Azure ML, SageMaker, GCP AI Platform (take your pick)
- Serving — TensorFlow Serving, TorchServe (the waiters of the ML world)
Let’s Get Hands-On: A Real Example
Enough theory. Let’s build something. We’ll train a simple model, track it with MLflow, and set up a basic deployment pipeline. You can follow along if you want — I’ll wait.
Step 1: Set Up MLflow
First, install MLflow and get it running locally:
pip install mlflow scikit-learn pandas numpy
mlflow ui
This spins up a web UI at http://localhost:5000. You’ll see it’s empty right now. We’ll fix that.
Step 2: Train a Model and Log Everything
Let’s train a crappy little model that predicts wine quality based on chemical features. Don’t worry about the data — scikit-learn has a built-in wine dataset.
Create a file called train.py:
import mlflow
import mlflow.sklearn
import numpy as np
from sklearn.datasets import load_wine
from sklearn.model_selection import train_test_split
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import accuracy_score, f1_score

# Load data — yes it's wine, no you can't drink it
data = load_wine()
X = data.data
y = data.target

# Split so we don't cheat on our test set
X_train, X_test, y_train, y_test = train_test_split(
    X, y, test_size=0.2, random_state=42
)

# Start an MLflow run
with mlflow.start_run(run_name="wine-forest-v1"):
    # Train a random forest — fancy name for "a bunch of decision trees"
    model = RandomForestClassifier(n_estimators=100, max_depth=5, random_state=42)
    model.fit(X_train, y_train)

    # Predict and evaluate
    preds = model.predict(X_test)
    acc = accuracy_score(y_test, preds)
    f1 = f1_score(y_test, preds, average="weighted")

    # Log parameters so future you knows what you did
    mlflow.log_param("n_estimators", 100)
    mlflow.log_param("max_depth", 5)

    # Log metrics so you can brag about accuracy
    mlflow.log_metric("accuracy", acc)
    mlflow.log_metric("f1_score", f1)

    # Save the model so you can deploy it later
    mlflow.sklearn.log_model(model, "model")

    print(f"Accuracy: {acc:.4f}, F1 Score: {f1:.4f}")
    print(f"Run ID: {mlflow.active_run().info.run_id}")
Run it:
python train.py
You should see something like:
Accuracy: 0.9722, F1 Score: 0.9721
Run ID: abc123def456...
Now go check the MLflow UI (http://localhost:5000). You’ll see your run logged with params, metrics, and even the model file. Neat, right?
Step 3: Serve the Model
Here’s where the magic happens. MLflow can serve your model as a REST API with one command:
mlflow models serve -m runs:/<RUN_ID>/model -p 5001 --no-conda
Replace <RUN_ID> with that ID from the output above. Now you’ve got a model running at http://localhost:5001/invocations.
Test it with a quick curl (you might need to install curl or use PowerShell’s Invoke-RestMethod):
curl -X POST http://localhost:5001/invocations \
  -H "Content-Type: application/json" \
  -d '{
    "inputs": [
      [13.2, 2.77, 2.51, 18.5, 96.0, 1.04, 2.55, 0.57, 1.47, 6.2, 1.05, 3.33, 820.0]
    ]
  }'
Boom. Your model just predicted a wine class over HTTP. You’re basically running a tech startup now.
Step 4: Containerize It (Fancy Talk for Docker)
You don’t want to run mlflow models serve on your production server. That’s amateur hour. Use Docker:
FROM python:3.9-slim

RUN pip install mlflow scikit-learn pandas numpy

COPY . /app
WORKDIR /app

EXPOSE 5001

CMD mlflow models serve \
  -m runs:/<RUN_ID>/model \
  -p 5001 \
  --host 0.0.0.0 \
  --no-conda
Build and run:
docker build -t wine-model .
docker run -p 5001:5001 wine-model
Now your model’s running in a container. It’ll work the same on your laptop, your server, or your buddy’s janky old desktop. Consistency!
Quick Tips Before You Go
1. Version Everything — Code, Data, Models
If it’s not versioned, it didn’t happen. Git is great for code, but for data you need something else. Enter DVC (Data Version Control), which is basically Git for your big honkin’ CSV files.
Set up DVC in your project:
pip install dvc
git init
dvc init
Now instead of committing giant CSV files to Git (please don’t do that), you track them with DVC:
dvc add data/raw/training_data.csv
git add data/raw/training_data.csv.dvc .gitignore
git commit -m "track training data with DVC"
Push that data to S3 (or GCS, or Azure, or a shared drive):
dvc remote add -d myremote s3://my-ml-bucket/data
dvc push
When your coworker clones the repo, they just run:
dvc pull
Boom — exact same data you used, no “works on my machine” drama.
You can do the same with models too:
dvc add models/random_forest.pkl
git add models/random_forest.pkl.dvc
git commit -m "track trained model"
dvc push
Now every model version is linked to exactly the data and code that produced it. Future you will be very grateful.
2. Automate Everything — CI/CD for ML
Don’t deploy models by hand. Seriously. Write a GitHub Actions workflow and sleep better at night.
Create .github/workflows/ml-pipeline.yml:
name: ML Pipeline

on:
  push:
    branches: [main]
  pull_request:
    branches: [main]

jobs:
  train-and-deploy:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v3

      - name: Set up Python
        uses: actions/setup-python@v4
        with:
          python-version: '3.9'

      - name: Install deps
        run: |
          pip install -r requirements.txt
          pip install pytest

      - name: Run tests
        run: pytest tests/

      - name: Train model
        run: python train.py

      - name: Run evaluation gates
        run: python check_model_quality.py

      - name: Deploy to staging
        if: github.ref == 'refs/heads/main'
        run: |
          mlflow models serve -m runs:/$(cat run_id.txt)/model -p 5001 &
          sleep 3
          curl -f http://localhost:5001/invocations -X POST \
            -H "Content-Type: application/json" \
            -d '{"inputs": [[13.2, 2.77, 2.51, 18.5, 96.0, 1.04, 2.55, 0.57, 1.47, 6.2, 1.05, 3.33, 820.0]]}'
And make a check_model_quality.py that gatekeeps your deploys:
import mlflow
import json

# Load latest run and check if accuracy is good enough
with open("run_id.txt") as f:
    run_id = f.read().strip()

client = mlflow.tracking.MlflowClient()
run = client.get_run(run_id)
accuracy = run.data.metrics.get("accuracy", 0)

min_acceptable = 0.85
print(f"Model accuracy: {accuracy:.4f}")

if accuracy < min_acceptable:
    print(f"Accuracy {accuracy:.4f} below threshold {min_acceptable}. Blocking deploy!")
    exit(1)

print("Model passes quality gate. Deploying...")
Now every push runs your pipeline, trains a model, checks if it’s good enough, and only deploys if it passes. No more “whoops, I deployed the broken one.”
3. Watch Your Models — Drift Detection
Models go bad. It’s not their fault — the world changes. Your customers start acting different, data shifts, and suddenly your 97% accurate model is making trash predictions.
Don’t wait for users to complain. Write a simple drift monitor:
import numpy as np
import mlflow
import json
from scipy.stats import ks_2samp

def detect_drift(reference_data: np.ndarray, new_data: np.ndarray, threshold: float = 0.05):
    """
    Run Kolmogorov-Smirnov test on each feature.
    If the distributions changed significantly, we've got drift.
    """
    drift_flags = []
    for i, col in enumerate(reference_data.T):
        stat, p_value = ks_2samp(reference_data[:, i], new_data[:, i])
        drifted = p_value < threshold
        drift_flags.append({
            "feature_index": i,
            "ks_statistic": float(stat),
            "p_value": float(p_value),
            "drifted": drifted
        })
    return drift_flags

# Load your training data as the reference distribution
ref_data = np.load("data/processed/reference_features.npy")

# Load some recent production data
prod_data = np.load("data/production/last_week_features.npy")

results = detect_drift(ref_data, prod_data)

drifted_features = [r for r in results if r["drifted"]]
if drifted_features:
    print("DRIFT DETECTED! Features that changed:")
    for f in drifted_features:
        print(f"  Feature {f['feature_index']}: p-value = {f['p_value']:.6f}")

    # Log drift to MLflow
    with mlflow.start_run(run_name="drift-check"):
        mlflow.log_metric("drifted_features", len(drifted_features))
        for f in drifted_features:
            mlflow.log_metric(f"feature_{f['feature_index']}_pval", f["p_value"])

    # Optionally trigger a retraining job
    print("Triggering retraining pipeline...")
else:
    print("All clear. No significant drift detected.")
Throw this in a cron job or a scheduled GitHub Action that runs weekly. Future you (at 2 AM, with a pager alert going off) will thank present you.
4. Keep It Reproducible
“Works on my machine” is a disease. The cure is pinning everything.
pip freeze > requirements.txt
But honestly, use a conda environment or Docker if you want to be really safe:
# environment.yml
name: mlops-project
channels:
  - conda-forge
  - defaults
dependencies:
  - python=3.9
  - pip
  - numpy=1.24
  - pandas=2.0
  - scikit-learn=1.2
  - mlflow=2.3
  - dvc=2.58
  - pip:
    - shap==0.41
    - pytest==7.4
Now your teammate just runs:
conda env create -f environment.yml
conda activate mlops-project
Same packages, same versions, same results. Magic.
5. Don’t Go Crazy
Start simple. A notebook + MLflow + a cron job is fine for your first project. You don’t need Kubernetes, you don’t need a dedicated MLOps platform. Add complexity when it hurts not to have it, not because the internet said you should.
6. Security Matters
Your model endpoint is not a public park. Put a lock on it.
Here’s a quick auth middleware for a Flask model server:
from flask import Flask, request, jsonify
import mlflow.pyfunc
import os

app = Flask(__name__)

API_KEY = os.environ.get("MODEL_API_KEY", "change-me-in-production")

model = mlflow.pyfunc.load_model("models/wine-classifier")

@app.before_request
def check_auth():
    token = request.headers.get("Authorization", "")
    if token != f"Bearer {API_KEY}":
        return jsonify({"error": "unauthorized"}), 401

@app.route("/invocations", methods=["POST"])
def predict():
    data = request.json
    inputs = data.get("inputs")
    preds = model.predict(inputs)
    return jsonify({"predictions": preds.tolist()})

if __name__ == "__main__":
    app.run(host="0.0.0.0", port=5001)
Now your clients need to pass a key:
curl -X POST http://localhost:5001/invocations \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer supersecretkey123" \
  -d '{"inputs": [[13.2, 2.77, 2.51, 18.5, 96.0, 1.04, 2.55, 0.57, 1.47, 6.2, 1.05, 3.33, 820.0]]}'
No key? No prediction. Simple.
Real Talk: The Hard Parts
Data Is Messy
Oh boy, is it ever. You’ll spend 80% of your time cleaning data. Here’s what your life looks like:
import pandas as pd
import numpy as np

# Load your "clean" data
df = pd.read_csv("data/raw/customer_data.csv")

# 1. Missing values — always
print("Missing values:")
print(df.isnull().sum())

# 2. Duplicate rows — always
dupes = df.duplicated().sum()
print(f"\nDuplicated rows: {dupes}")

# 3. Wild outliers — always
print("\nSOG outliers (should be 0-40):")
print(df[df["sog"] > 40][["mmsi", "sog", "timestamp"]].head(10))

# 4. Strings where numbers should be — always
print("\nNon-numeric values in numeric columns:")
for col in ["sog", "cog", "rate_of_turn"]:
    non_numeric = pd.to_numeric(df[col], errors="coerce").isna()
    if non_numeric.any():
        print(f"  {col}: {non_numeric.sum()} non-numeric values")

# 5. Timestamps that make no sense — always
df["timestamp"] = pd.to_datetime(df["timestamp"], errors="coerce")
future_dates = df[df["timestamp"] > pd.Timestamp.now()]
print(f"\nFuture timestamps (time travelers?): {len(future_dates)}")
This isn’t even the hard stuff. Wait till you get nested JSON, images with wrong labels, and text data that looks like someone fell asleep on the keyboard.
You don’t fix this once. You build pipelines that keep fixing it forever because new data will always bring new problems. That’s the gig.
Models Are Black Boxes
Your model says “this customer will churn.” Why? Who knows. It’s just a pile of matrices doing matrix things.
Use SHAP to get some answers:
import shap
import numpy as np
from sklearn.ensemble import RandomForestClassifier
from sklearn.datasets import load_wine

# Train a model (or load your existing one)
data = load_wine()
model = RandomForestClassifier(n_estimators=100, max_depth=5, random_state=42)
model.fit(data.data, data.target)

# Explain what the model is doing
explainer = shap.TreeExplainer(model)
shap_values = explainer.shap_values(data.data)

# Pick one prediction and explain it
sample_idx = 5
print(f"Prediction for sample {sample_idx}: {model.predict([data.data[sample_idx]])[0]}")
print(f"Actual label: {data.target[sample_idx]}")
print("\nFeature contributions for this prediction:")
feature_importance = list(zip(data.feature_names, shap_values[0][sample_idx]))
feature_importance.sort(key=lambda x: abs(x[1]), reverse=True)
for name, val in feature_importance[:5]:
    print(f"  {name}: {val:+.4f}")

# Plot summary (if you're in a notebook)
shap.summary_plot(shap_values[0], data.data, feature_names=data.feature_names)
Now instead of saying “the model said so,” you can say “the model flagged this because alcohol content is unusually high and malic acid is low.” That’s way more useful when explaining to a stakeholder who doesn’t care about your random forest, they just want to know why the system did what it did.
Scale Is Painful
Your laptop can handle 1,000 rows. Production handles 10 million. Stuff breaks.
Here’s a load test using the gloriously simple locust library. Install it with pip install locust, then create locustfile.py:
from locust import HttpUser, task, between
import json
import random

class ModelUser(HttpUser):
    wait_time = between(0.5, 2)

    @task
    def predict(self):
        # Send random wine features to the model endpoint
        features = [
            random.uniform(11, 15),   # alcohol
            random.uniform(1, 5),     # malic_acid
            random.uniform(1, 4),     # ash
            random.uniform(10, 30),   # alcalinity_of_ash
            random.uniform(70, 150),  # magnesium
            random.uniform(0.5, 2.5), # total_phenols
            random.uniform(0.5, 3.5), # flavanoids
            random.uniform(0.1, 1.5), # nonflavanoid_phenols
            random.uniform(1, 4),     # proanthocyanins
            random.uniform(3, 15),    # color_intensity
            random.uniform(0.5, 2),   # hue
            random.uniform(1, 4),     # diluted_wines
            random.uniform(400, 1500) # proline
        ]

        self.client.post(
            "/invocations",
            json={"inputs": [features]},
            headers={"Authorization": "Bearer test-key"},
        )
Run it:
locust -f locustfile.py --host http://localhost:5001
Open http://localhost:8089, spawn 100 users, and watch your model server sweat. If response times spike past 2 seconds or you start getting 503 errors, you’ve got a scaling problem. Now you know. Fix it before your boss finds out the hard way.
You Need a Translator
Here’s the classic breakdown in communication:
# Data scientist writes:
model.fit(X_train, y_train)
# "I need the latest training data pulled, cleaned, and transformed before we can deploy."

# DevOps reads:
# "Put this in a container, expose an API, wire it to the load balancer, set up auto-scaling, and add monitoring."

# Neither understands what the other said.
The solution? Have someone (or yourself) learn both sides. Write a README that explains in plain English what your pipeline needs:
# Deployment Instructions for Ops Team

## What This Model Does
Classifies wine varieties based on chemical analysis.

## Input Requirements
- 13 numeric features (see `data/schema.json` for exact format)
- No missing values allowed — handle before sending
- Feature order must match exactly

## Output Format
```json
{"predictions": [0, 1, 2]}  // 0=class_0, 1=class_1, 2=class_2
Environment Variables Needed
MODEL_API_KEY— set this, don’t use the default
Resource Requirements
- 2 GB RAM minimum
- No GPU needed (it’s just a random forest)
- Starts in ~3 seconds
How to Know It’s Healthy
/healthreturns 200- Response time under 200ms ```
Bridge the gap. Write docs. Use tools both sides understand (Docker helps a lot). Get everyone in the same room once a week.
Regulations Are a Thing
GDPR says users can request their data be deleted. If you trained your model on that data, do you have to retrain? HIPAA says healthcare data needs special handling. If your model processes PHI, your whole pipeline needs to be compliant.
There’s no code snippet that solves this. You need to:
# At minimum, log who accessed what, when, and why
import logging
import json
from datetime import datetime

def log_prediction_access(user_id: str, input_shape: tuple, model_version: str):
    log_entry = {
        "timestamp": datetime.utcnow().isoformat(),
        "user_id": user_id,  # anonymized if needed
        "input_shape": input_shape,
        "model_version": model_version,
        "action": "prediction"
    }
    logging.info(json.dumps(log_entry))
    # Store this somewhere immutable — S3, database, whatever
    # Keep it for as long as your compliance requires (usually 1-7 years)
And make sure you can answer “what data did we train on?” at any time. That’s where DVC from tip #1 comes in clutch.
Where to Start
Alright, you’re not overwhelmed yet? Let’s build a real starter project step by step.
The Starter Template
Here’s a project structure that scales from “toy” to “real”:
ml-project/
├── .github/
│   └── workflows/
│       └── ml-pipeline.yml        # CI/CD
├── data/
│   ├── raw/                       # untouched data
│   ├── processed/                 # cleaned data
│   └── predictions/               # model outputs
├── models/                        # trained model files
├── notebooks/                     # exploration (messy, allowed)
├── src/
│   ├── data/
│   │   ├── load_data.py
│   │   └── preprocess.py
│   ├── models/
│   │   ├── train.py
│   │   └── predict.py
│   ├── monitoring/
│   │   └── drift_detection.py
│   └── deploy/
│       ├── app.py                 # Flask/FastAPI server
│       └── Dockerfile
├── tests/
│   ├── test_preprocess.py
│   └── test_model.py
├── environment.yml                # pinned deps
├── Makefile                       # common commands
└── README.md
The Makefile
So you don’t have to remember commands:
.PHONY: setup clean train deploy test

setup:
	conda env create -f environment.yml
	conda activate ml-project
	dvc pull

data:
	python src/data/load_data.py
	python src/data/preprocess.py

train: data
	python src/models/train.py

serve:
	mlflow models serve -m models/ --no-conda -p 5001

test:
	pytest tests/

deploy: test
	@echo "Building Docker image..."
	docker build -t ml-model:latest -f src/deploy/Dockerfile .
	@echo "Pushing to registry..."
	docker tag ml-model:latest myregistry.azurecr.io/ml-model:$$(git rev-parse --short HEAD)
	docker push myregistry.azurecr.io/ml-model:$$(git rev-parse --short HEAD)

drift-check:
	python src/monitoring/drift_detection.py

clean:
	find . -type d -name __pycache__ -exec rm -rf {} + 2>/dev/null || true
	rm -rf data/processed/* models/*
Now your workflow is just:
make setup     # one-time
make train     # train the model
make test      # run tests
make deploy    # ship it
Your First Week Plan
Day 1-2: Set up experiment tracking. Add MLflow to your existing notebook. Log one metric. See it appear in the UI. That’s a win.
Day 3-4: Add version control for your data with DVC. Pick one dataset and get it tracked. Then dvc push it somewhere.
Day 5: Write one test for your preprocessing code. Something simple like “test that there are no missing values after cleaning.” Run it. Watch it pass.
Day 6: Automate that test with a GitHub Action. Push a commit, see the test run in the Actions tab. High-five yourself.
Day 7: Rest. You’ve done more MLOps this week than most teams do in a month.
The Golden Rule
Don’t try to do everything at once. Pick the thing that hurts most right now and fix that one thing. If you lose model files all the time, version them. If deployment takes three hours, automate it. If you don’t know when models degrade, add drift detection.
MLOps is not a destination. It’s just the stuff you do to keep your models from being useless. Do a little bit at a time, and eventually you’ll look back and realize you’ve built something that doesn’t fall over constantly. That’s the dream.
Good luck out there. You got this.
Comments
Leave a comment